
Traffic Shaping and QPS Optimization for SSPs and Ad Networks: Reducing Cloud Egress Costs
An uncompressed OpenRTB 2.6 bid request carrying a multi-node SupplyChain (schain) object, extended user identity (user.ext.eids) arrays, IAB Global Privacy
An uncompressed OpenRTB 2.6 bid request carrying a multi-node SupplyChain (schain) object, extended user identity (user.ext.eids) arrays, IAB Global Privacy Platform (GPP) strings, and Connected TV (CTV) content metadata averages 4.5 KB to 6.8 KB on the wire. When an exchange ingests 200,000 inbound publisher queries per second (QPS) and executes an unthrottled fan-out across 25 participating tier-1 DSPs, outbound traffic scales to 5,000,000 QPS. Even with HTTP/2 header compression and GZIP payload encoding reducing the wire footprint to 1.8 KB per outbound request, that fan-out generates 72 gigabits per second (Gbps) of continuous Wide Area Network (WAN) egress, or roughly 23.6 petabytes of outbound data transfer every month.
At standard cloud hyperscaler egress rates between $0.02 and $0.05 per gigabyte, unoptimized bidstream fan-out costs an SSP or ad network $470,000 to $1.18 million monthly in bandwidth charges alone, before accounting for the compute tax of JSON serialization, memory allocation, and TLS socket management. For a multi-format monetization platform operating across Web, Mobile App, and CTV, outbound bandwidth is frequently the single largest variable infrastructure expense on the balance sheet.
Controlling this cost without depressing publisher yield or auction bid density requires deterministic traffic shaping. By combining pre-serialization filtration, multi-dimensional buyer profiling, predictive latency shedding, in-cluster containerized curation, and regional Point of Presence (PoP) routing, engineering teams can reduce outbound cloud egress by 45% to 65% while preserving over 99.4% of gross clearing revenue.
The Economics of Queries Per Second (QPS) in Programmatic Exchanges
Programmatic exchange economics are governed by the asymmetry between inbound supply requests and outbound demand fan-out. A single pageview running client-side Prebid.js 11.x or a single CTV ad break triggered via Server-Side Ad Insertion (SSAI) does not map to a single outbound HTTP POST. In a multi-slot Web wrapper or a multi-pod VAST 4.3 CTV request, an SSP must evaluate multiple imp objects across dozens of demand seats, deals, and regional endpoints.
The primary financial metric for infrastructure efficiency in an exchange is Effective Revenue Per Million Outbound Queries (eRPMQ), calculated alongside the marginal cost of transmitting 1,000,000 bid requests (cPMQ). When an SSP forwards a 5 KB OpenRTB 2.6 payload to a tier-1 DSP that responds with an HTTP 204 (No Content) 99.8% of the time, the exchange absorbs 100% of the CPU serialization cost and cloud egress fee while generating zero clearing margin. Across billions of daily auctions, three technical factors compound this unit-cost pressure:
- OpenRTB 2.6 Payload Expansion: Modern bid requests are significantly heavier than legacy OpenRTB 2.5 payloads. Passing CTV ad pod parameters (
podid,poddur,maxseq,poddur), device attestation signals, multiple alternative identity graphs insideuser.ext.eids, and completeschainnodes routinely pushes raw JSON payloads past 6 KB. - Serialization and Compression CPU Overhead: In high-throughput Prebid Server Go or Java environments, marshaling an in-memory request struct into a JSON byte array and running
flateorgzipcompression consumes between 28% and 40% of total CPU cycles. Compressing payloads saves WAN egress bytes but spikes vCPU utilization, creating a direct trade-off between compute instances and network transfer bills. - Cross-Availability Zone (Cross-AZ) Data Transfer: Within major cloud providers, traffic passing between Availability Zones in the same region (for example, from an ingress load balancer in
us-east-1ato an auction pod inus-east-1b, and out through a NAT gateway inus-east-1c) incurs $0.01 per gigabyte in each direction before the packet ever exits to the public internet.
At Sky Boosts, maintaining reliable Net-30 and Net-60 payment terms for publishers across Web, Mobile App, and CTV requires strict control over these underlying infrastructure unit costs. Our high-QPS auction infrastructure enforces strict ingress hygiene before any fan-out occurs. Because we monetize 100% Google-friendly inventory (strictly excluding alcohol, gambling, adult, tobacco, and restricted content categories) and validate every impression through HUMAN and Pixalate Invalid Traffic (IVT) pre-bid filters at the network edge, non-compliant and bot-driven traffic is terminated prior to auction initialization. Combining clean, verified supply with intelligent outbound traffic shaping ensures that neither our exchange nor our demand partners waste compute cycles on non-monetizable QPS.
Pre-Bid Filtering: Dropping Low-Probability Requests Before Outbound Serialization
The most common architectural error in custom Prebid Server forks and proprietary SSP auction engines is executing traffic filtering too late in the request lifecycle. In a naive request pipeline, the auction engine parses the inbound publisher request, clones the master OpenRTB BidRequest object for every active demand partner, applies bidder-specific request mutations (such as mapping placement IDs or converting currency floors), serializes the mutated struct into JSON, and only then evaluates whether the outbound HTTP client has available QPS capacity.
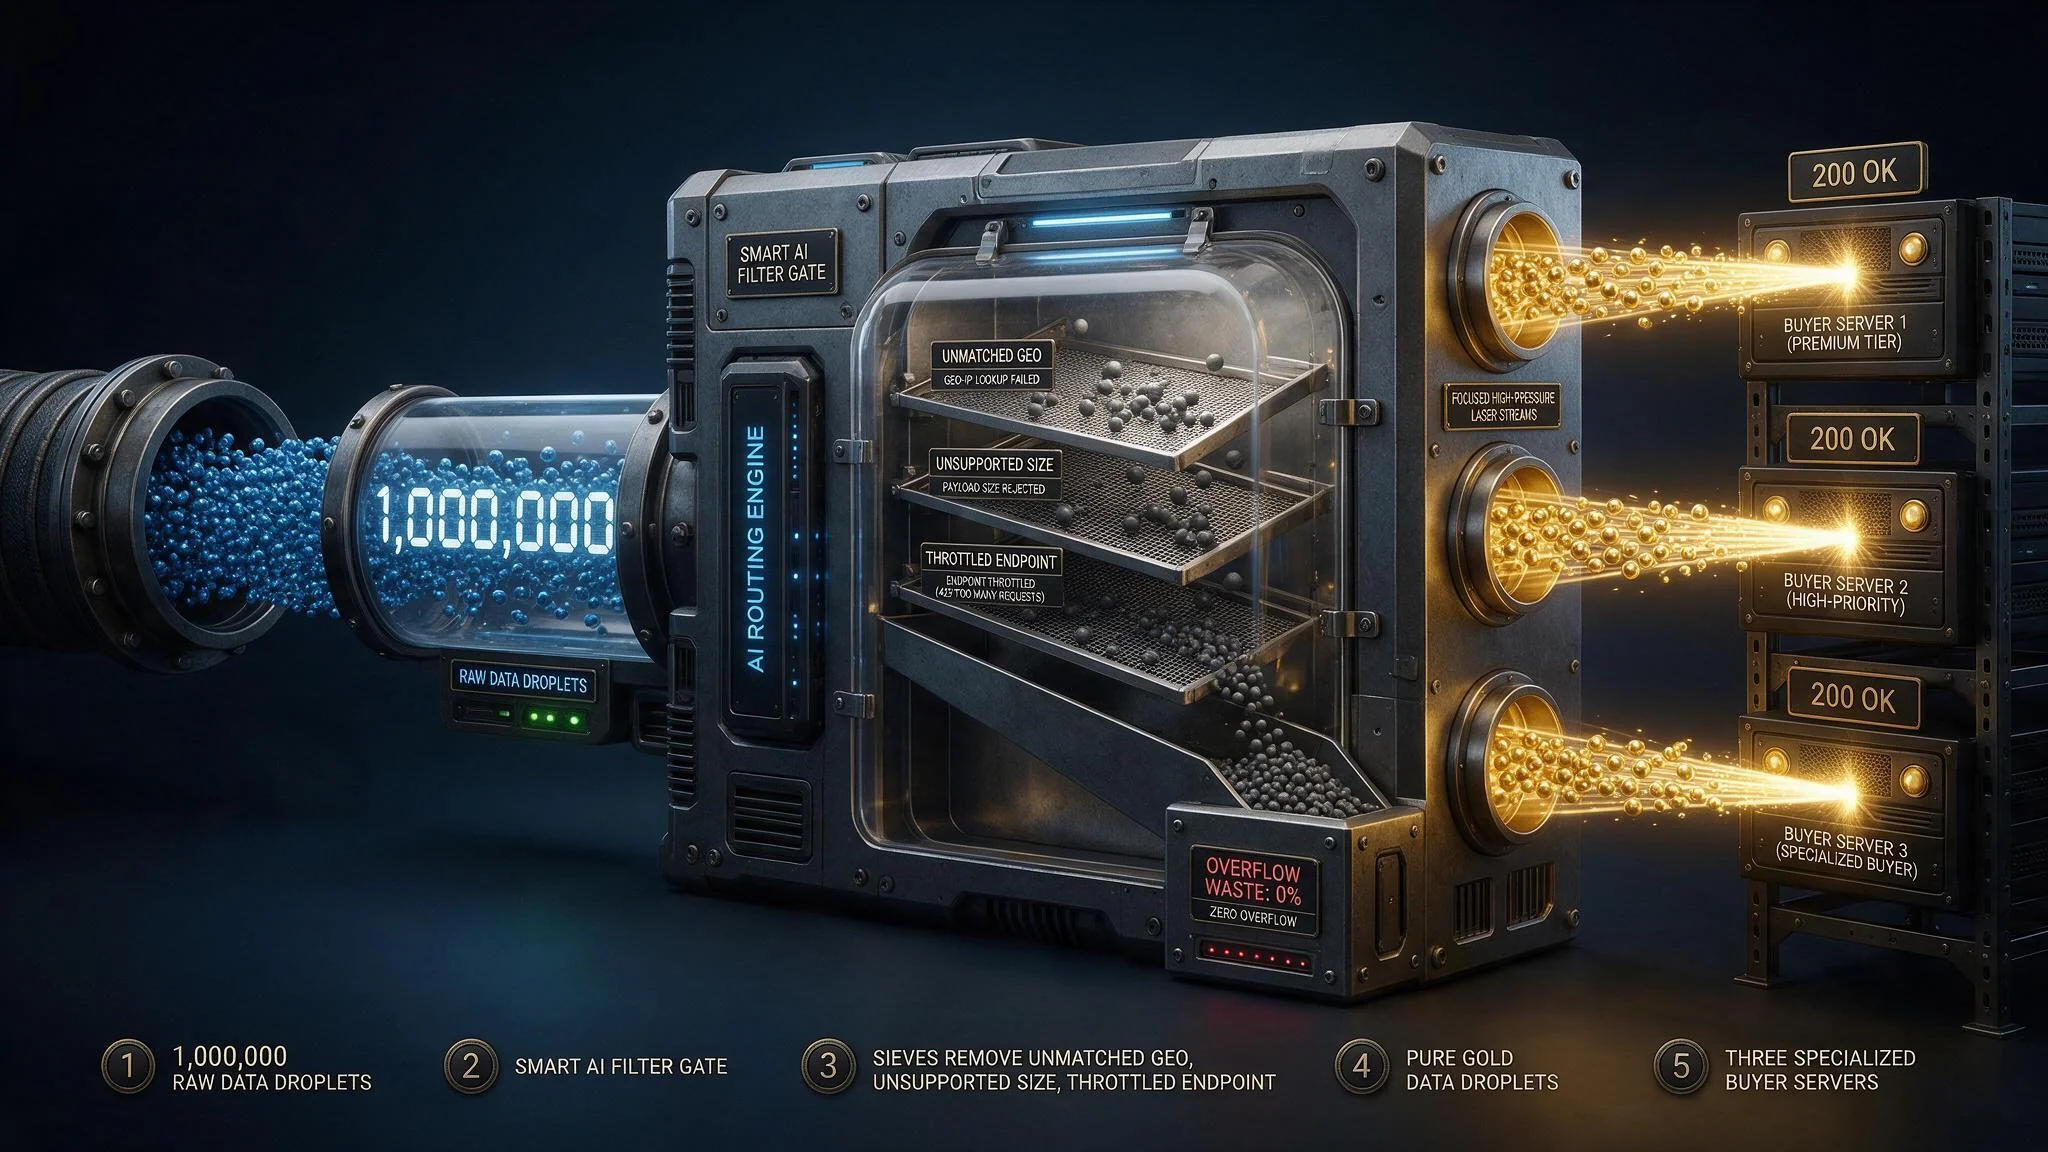
To eliminate wasted CPU and egress overhead, pre-bid filtering must execute as a zero-allocation gate immediately after inbound request validation and privacy regulation parsing, but strictly before per-bidder struct cloning and JSON marshaling. We divide the internal SSP processing pipeline into four discrete cost tiers:
- Stage 0 (Edge Ingress and IVT Gate): TLS termination, HTTP header inspection, HUMAN/Pixalate device and IP reputation lookup, and malformed payload rejection. Cost: minimal memory allocation, zero outbound egress.
- Stage 1 (In-Memory Pointer Evaluation): Read-only inspection of the parsed OpenRTB 2.6 request pointers (
imp,device,site/app,user,regs) against each demand partner's multidimensional buying profile and live endpoint health state. Cost: sub-microsecond bitwise and hash-map lookups. - Stage 2 (Bidder-Specific Mutation and Serialization): Deep-copying the
BidRequeststruct, injecting Private Marketplace (PMP)dealidarrays, adjusting bid floors, and marshaling the structure into a UTF-8 JSON buffer. Cost: high heap allocation, garbage collection pressure, and significant CPU cycles. - Stage 3 (Compression and Wire Dispatch): GZIP stream compression, HTTP/2 frame allocation, and outbound WAN transmission. Cost: peak CPU and full cloud egress billing.
By terminating low-probability bidder fan-outs at Stage 1, an SSP avoids 100% of the Stage 3 cloud egress charge and roughly 85% of the Stage 2 compute overhead. Even when multiple bidders share an identical underlying payload structure, pre-serialization filtering ensures that byte buffers are only constructed for demand seats with a statistically viable probability of returning a competitive bid.
Geo-Device-Format Matrix Matching Against DSP Buying Profiles
Tier-1 DSPs do not bid uniformly across the global programmatic supply graph. A given DSP seat may bid aggressively on US and UK iOS in-app rewarded video (device.devicetype: 4, imp.video.rwdd: 1) and Samsung Tizen or Roku CTV SSAI inventory (device.devicetype: 3), while bidding 0.00% of the time on mobile web display banners in Latin America when no matched user ID (user.ext.eids) or Google Ad Manager (GAM 360) PPID is present. Static QPS caps at the DSP account level are too blunt to capture these nuances; a flat cap simply drops high-value CTV requests alongside low-value banner requests once the ceiling is reached.
Instead, production traffic shapers evaluate a dynamic multi-dimensional feature matrix for every candidate DSP adapter. Every 300 seconds, a background aggregation pipeline queries real-time auction telemetry (typically stored in ClickHouse or streamed via Apache Kafka) to compute historical bid rate, win rate, and expected eRPMQ across a composite key of six dimensions:
- Geography: ISO-3166-1 alpha-3 country code (
device.geo.country) and region/DMA for primary markets. - Device Type and OS: OpenRTB 2.6
device.devicetype(Mobile/Tablet, Personal Computer, Connected TV, Set-Top Box) paired withdevice.os(iOS, Android, tvOS, Roku, Tizen, webOS). - Media Format and Placement: Banner (standard IAB sizes vs. high-impact), Video (VAST 4.3 instream/outstream, placement type
imp.video.plcmt), Native, or Audio. - Identity and Consent State: Presence of matched universal IDs in
user.ext.eids, Apple ATT status (device.ext.atts), and valid IAB GPP or TCF v2.2 consent strings. - Supply Channel: Prebid.js 11.x client-side header bidding, Prebid Mobile SDK, Google Open Bidding / MCM inventory, or direct CTV SSAI integration.
- Floor Price Bucket: Discretized bid floor tiers (
imp.bidfloor) relative to historical clearing prices for that slice of inventory.
When an inbound request enters Stage 1 evaluation, the traffic shaper hashes these six attributes into a 64-bit integer key and performs an atomic lock-free lookup against the bidder's active profile table. If the historical bid rate falls below a configured profitability threshold (for example, less than 0.04% bid density with an eRPMQ below the cloud egress cost threshold), the request is throttled.
Crucially, the filter must never drop 100% of traffic for a suppressed bucket permanently. If a buyer launches a new regional campaign at 09:00 UTC, a 100% block would prevent the SSP from ever observing the DSP's new bidding behavior, creating a permanent blind spot. To solve this, our DSP partnership integration architecture applies an epsilon-greedy exploration rate (typically 1.5% to 3.0% pass-through on throttled buckets). This low-volume exploration stream continuously probes the DSP with minimal egress cost; the moment the telemetry pipeline detects consecutive valid bids in a previously dormant slice, the matrix automatically promotes that bucket to 100% pass-through within seconds.
package trafficshaper

import (
	"hash/fnv"
	"math/rand/v2"
	"sync/atomic"
)

type BucketStats struct {
	BidRate     float64
	ExpectedRPM float64
	PassRate    float64 // 1.0 = full pass, 0.02 = 2% exploration probe
}

type ShaperMatrix struct {
	profiles atomic.Pointer[map[uint64]BucketStats]
	minRPMQ  float64
}

func ComputeMatrixKey(dspID, country, os, format string, devType int, hasEID bool) uint64 {
	h := fnv.New64a()
	h.Write([]byte(dspID + "|" + country + "|" + os + "|" + format))
	var flags [2]byte
	flags[0] = byte(devType)
	if hasEID {
		flags[1] = 1
	}
	h.Write(flags[:])
	return h.Sum64()
}

// ShouldDispatch evaluates before OpenRTB struct cloning and JSON serialization.
func (s *ShaperMatrix) ShouldDispatch(key uint64, dealCount int) bool {
	if dealCount > 0 {
		return true // Always bypass traffic shaping for active PMP/PG deals
	}
	table := s.profiles.Load()
	if table == nil {
		return true
	}
	stats, exists := (*table)[key]
	if !exists {
		return rand.Float64() < 0.05 // 5% cold-start discovery sampling
	}
	if stats.ExpectedRPM >= s.minRPMQ {
		return true
	}
	return rand.Float64() < stats.PassRate
}
Predictive Throttling During DSP Endpoint Latency Spikes
Matrix matching optimizes for historical buying relevance, but it cannot protect an exchange against real-time infrastructure degradation on the buy side. When a DSP cluster experiences garbage collection pauses, regional load-balancer saturation, or downstream database locks, its endpoints rarely fail cleanly with immediate HTTP 503 responses. Instead, response latency degrades gradually, pushing 95th and 99th percentile (p95/p99) round-trip times past the SSP's auction timeout window (typically 100ms to 150ms for Web/Mobile display, and 200ms to 300ms for CTV VAST 4.3 video auctions).
Late bids are the single most destructive inefficiency in programmatic networking:
- The SSP pays 100% of the outbound cloud egress fee to transmit the OpenRTB 2.6 request.
- The SSP pays the inbound network processing cost when the DSP finally writes the response bytes to the socket 15ms after the auction has already closed.
- The timed-out connection occupies an active HTTP/2 stream slot and file descriptor during the stall.
- The publisher and SSP earn zero revenue from the response because the winning creative has already been dispatched to Google Ad Manager (GAM 360), the GMA Next-Gen SDK, or the CTV SSAI stitcher.
To prevent timeout cascades, our auction engines implement predictive latency throttling using an Exponentially Weighted Moving Average (EWMA) of endpoint RTT paired with a sliding-window timeout counter. Rather than waiting for timeouts to breach a hard circuit-breaker threshold (which causes abrupt QPS oscillation and severe sawtooth load patterns on the recovering DSP), the traffic shaper dynamically raises the required minRPMQ threshold as a continuous function of p95 latency.
When a DSP endpoint's p95 latency rises from 65ms toward the 120ms auction deadline, the shaper progressively sheds the lowest-value QPS tiers first. Low-floor outstream or international display requests are dropped immediately, reducing concurrent load on the struggling DSP endpoint, while high-floor CTV ad pod requests, PMP deals, and identity-rich US/EU mobile app impressions continue to flow. As the reduced QPS load allows the DSP's internal queues to drain and p95 latency recovers below 80ms, the dynamic floor automatically relaxes back to baseline.
Evaluating Emerging Containerized Bidstream Processing (IAB ARTF v1.0)
Even with highly tuned internal matrix filters, traditional programmatic curation and DSP-side pre-filtering still suffer from an architectural separation between the SSP host environment and external decisioning logic. Historically, if a curation provider, data enrichment partner, or DSP wanted to apply proprietary filtering or audience segmentation rules to the bidstream, the SSP had to serialize the OpenRTB payload and transmit it over the public internet to an external endpoint. This model duplicates cloud egress costs and consumes 15ms to 40ms of precious auction clock time on network transit.
To eliminate this architectural bottleneck, the IAB Tech Lab standards body introduced the Agentic Real Time Framework (ARTF v1.0), which defines containerized runtime standards deployed directly inside host SSP and exchange infrastructure to execute real-time bidstream filtering, curation, and mutation with minimal network latency and egress cost.
Under the IAB ARTF v1.0 architecture, external demand partners and curation agents package their decisioning models as lightweight, OCI-compliant containers that run directly within the SSP's local Kubernetes worker nodes. Instead of serializing JSON over WAN HTTP connections, the SSP auction engine communicates with the co-located ARTF container over high-speed local gRPC via Unix domain sockets (unix:///var/run/artf/agent.sock) or shared memory buffers within the same physical host.
apiVersion: artf.iabtechlab.com/v1
kind: AgentRuntimeManifest
metadata:
  agentName: "dsp-edge-traffic-filter"
  protocolVersion: "1.0"
spec:
  transport:
    type: "grpc-uds"
    socketPath: "/var/run/artf/dsp_filter.sock"
    maxExecutionBudgetMs: 3
  capabilities:
    - "BIDSTREAM_FILTER"
    - "DEAL_CURATION_INJECTION"
  resourceLimits:
    cpu: "2000m"
    memory: "4Gi"
    networkEgress: "DENY_ALL"
Because the ARTF container executes with a strict DENY_ALL external network policy inside the same cloud availability zone and node as the SSP auction pod, zero cloud egress fees or cross-AZ transfer charges are incurred during evaluation. The containerized agent inspects the in-memory representation of the OpenRTB 2.6 request within a strict 2ms to 3ms execution budget and returns a binary dispatch directive or injects curated imp.pmp.deals identifiers. If the agent signals a drop, the SSP suppresses outbound WAN serialization to that DSP entirely, achieving 100% alignment between the buyer's exact bidding logic and the exchange's outbound bandwidth consumption.
Regional Data Center Routing (US-East, EU-Central, APAC) to Stay Under 100ms RTT
Software-level QPS optimization must be paired with physical network topology engineering. A perfectly filtered OpenRTB 2.6 bid request will still time out if the packet must traverse transoceanic fiber links twice during an auction. Given the speed of light in fiber-optic cable (roughly 200 kilometers per millisecond, before router queueing delays), routing an impression generated on an LG webOS television in Frankfurt to an SSP cluster in Virginia (us-east-1), and then fanning out to a DSP endpoint back in Amsterdam adds over 170ms of baseline physical latency, guaranteeing an auction timeout.
Operating a low-latency, cost-efficient exchange requires localized regional PoPs aligned with the physical peering hubs of tier-1 DSPs:
- North America (US-East and US-West): Primary compute clusters in Ashburn, Virginia (
us-east-1) and Portland/Hillsboro, Oregon (us-west-2) to cover domestic Web, Mobile App, and CTV supply with sub-25ms ingress latency. - Europe (EU-Central): High-density clusters in Frankfurt (
eu-central-1) and Amsterdam, keeping GDPR/TCF v2.2 traffic strictly within European borders and under 15ms RTT to regional DSP exchanges. - Asia-Pacific (APAC): Dual regional hubs in Tokyo (
ap-northeast-1) and Singapore (ap-southeast-1) to terminate high-volume mobile app and CTV connections across Japan, Southeast Asia, Australia, and India without trans-Pacific backhaul.
At the ingress layer, Anycast DNS and latency-based GeoDNS direct publisher requests from Prebid.js 11.x browsers, GMA/Prebid Mobile SDKs, and CTV SSAI stitchers to the nearest regional PoP. Once inside the regional cluster, the SSP's outbound router enforces strict regional affinity: an auction executing in eu-central-1 only fans out to DSP endpoints hosted in European data centers. Inter-continental outbound fan-out is disabled by default and only permitted for asynchronous operations that do not block the real-time bid path, such as cookie-sync pixels or out-of-band win notifications (burl/nurl).
Within each regional cluster, maintaining sub-100ms end-to-end RTT and minimizing egress overhead depends on three transport-layer practices:
- Persistent HTTP/2 and HTTP/3 Connection Pooling: Establishing a new TCP and TLS 1.3 handshake requires 1 to 2 round-trips, adding 15ms to 40ms of latency and significant packet overhead. SSP worker nodes must maintain pre-warmed, long-lived HTTP/2 connection pools to every DSP endpoint, multiplexing hundreds of concurrent OpenRTB 2.6 requests over shared TCP sockets with HPACK header compression enabled.
- Topology-Aware Kubernetes Routing: Using Kubernetes
service.kubernetes.io/topology-mode: Auto, all internal communication between ingress load balancers, auction pods, and ARTF v1.0 sidecars is pinned to the same physical Availability Zone, eliminating the $0.01/GB cross-AZ cloud transit tax entirely. - Payload Stripping per Bidder Capability: Before Stage 2 serialization, the outbound adapter strips OpenRTB 2.6 extension fields that a specific DSP does not ingest. If a DSP only processes two specific universal IDs, the adapter prunes the remaining twelve
user.ext.eidsobjects from that specific outbound payload, shrinking wire size by up to 35% per request.
For AdOps architects and platform engineers, the operational takeaway is straightforward: treat every outbound kilobyte as a billable capital allocation decision. By auditing your exchange's eRPMQ per demand partner, moving multi-dimensional matrix filtration upstream of JSON serialization, deploying predictive EWMA latency throttling, adopting local containerized filtering via IAB ARTF v1.0, and enforcing strict AZ-pinned regional routing, you can cut cloud network egress costs in half while accelerating auction clearing speeds across every supply channel.